
How to Handle Backups (Import, Export, Automatic Backups)
Backups in Teamscale are very helpful when upgrading to a new Teamscale version or to mitigate the risk of potential data loss.
Automatic Backups
We highly recommend automatic backups to be enabled for all production use of Teamscale. See the respective section below on how to configure automatic backups.
Exporting Backups
Depending on your needs (e.g., during an update), you can export only global data (like users, groups, settings, permissions, dashboards), project data (e.g., tolerations, false positives, baselines and external findings), or both. Furthermore, you can choose to only export project data for some rather than all of your projects. The project list offers the projects that you may back up, which the Backup Project Data permission controls.
To create a backup, first navigate to Admin > Backup. Here you have two options to initiate the backup:
When you choose Export Backup, your browser will download a single backup ZIP and you can store it locally.
Alternatively, you can provide a file-system path (or S3 URI) to let Teamscale store your backup there. This way is often preferable if the backup ZIP would be too large to comfortably download.
Rescue backup on startup
Under certain error conditions (e.g. database corruption) the above mechanism may not work anymore for exporting backups. In this case the command line argument -b <PATH-TO-BACKUP-FILE> passed to the teamscale.sh or .bat file can be used to dump a rescue backup during the startup of Teamscale.
Backup Export Options
By default, a backup contains everything Teamscale needs to restore an instance. Export options let you leave parts of that data out, which is useful when a backup has grown too large to download or store comfortably. The most common reason for a large backup is years of accumulated coverage, findings and metrics uploads.
External Storage Backends
External data stored in an external storage backend never enters a backup, so the pruning rules below cannot shrink it any further. Moving projects there keeps backups small permanently and lets the storage system retire old uploads for you.
Export options apply only to the single export you start, and they only change what is written into the backup file. The data on the running instance is never touched. Automatic backups always contain all data and cannot be slimmed down this way.
Use With Caution
Export options remove data from a backup, so an instance might not be restorable from a backup created with them. Always keep at least one recent backup exported without any export options, so you can fall back to it if a slimmed-down backup turns out to be missing data you need.
To configure export options, navigate to Admin > Backup and open the Export Options tab (1). The same options are available under Load Backup From Other Instance in the Export Options for the Remote Instance section, where they apply to the backup the remote instance creates for you.
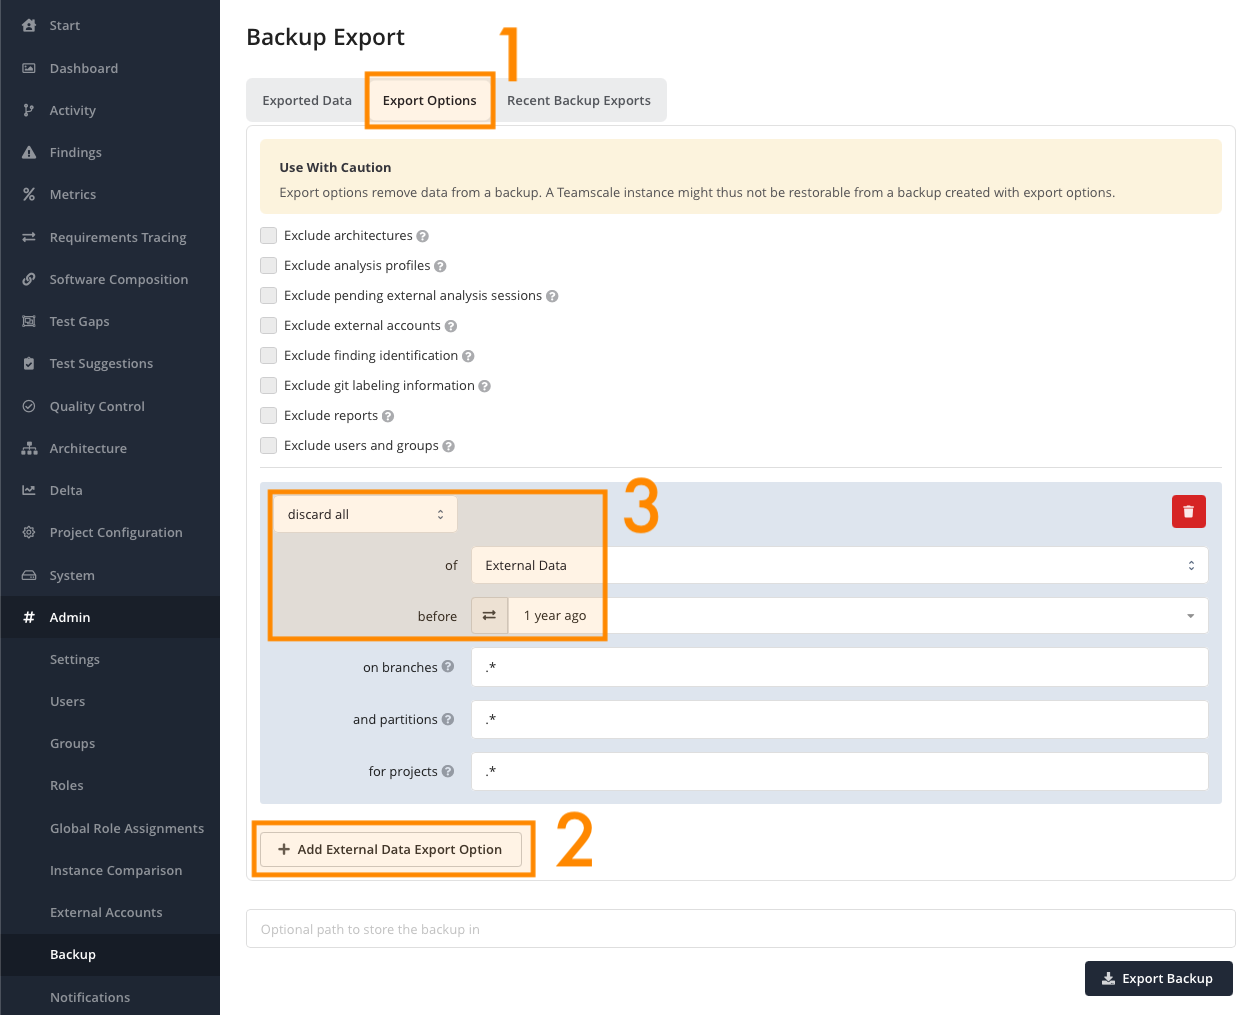
Excluding Categories of Data
The checkboxes leave out whole categories of data:
| Option | Excluded data |
|---|---|
| Exclude architectures | All architecture definitions. |
| Exclude analysis profiles | All analysis profiles. |
| Exclude pending external analysis sessions | External analysis sessions that are still open, that is, uploads that were started but not yet committed. |
| Exclude external accounts | All external accounts, together with the credentials stored in them. |
| Exclude finding identification | The data Teamscale uses to recognize a finding across commits. Findings tracking is less accurate after importing such a backup. |
| Exclude git labeling information | The historic data that maps Git commits to branches. Branch assignments of commits can become unstable after importing such a backup. |
| Exclude reports | All quality reports, including their slides. |
| Exclude users and groups | Users, groups, and everything tied to them: API access keys, permissions, user activity, dashboard favorites, and avatars. |
Pruning Uploaded Data by Age
Coverage, findings and metrics uploads, as well as architecture uploads, are usually the largest part of a backup, because Teamscale keeps every single upload. Rather than dropping them entirely, you can thin out the old ones and keep the recent ones.
Choose Add External Data Export Option (2) to add a rule (3). Each rule consists of these parts:
| Part | Meaning |
|---|---|
| Action | What happens to the matched uploads: discard all, keep only one per day, keep only one per week, or keep all. |
| of | Which kind of upload the rule applies to: External Data (coverage, findings, metrics, test results), Architectures, or both. |
| before | Only uploads older than this point in time are affected. The switch button left of the field toggles between a relative timespan such as 1 year ago and a concrete calendar date. |
| on branches | A regular expression that must match the full branch name of the upload. |
| and partitions | A regular expression that must match the full partition name. Partitions exist for external data only, so this has no effect on architecture uploads. |
| for projects | A regular expression that must match the full project ID. |
You can add several rules. For each upload, the first rule from top to bottom whose parts all match decides what happens to it. Uploads that no rule matches are kept. A keep all rule placed above a broader rule therefore lets you carve out an exception, for example to preserve the uploads of one project while pruning all others.
The two thinning actions keep one upload per day or per week, counted separately for each branch and partition. For architecture uploads, the content of a discarded upload is merged into the next upload that is kept on the same branch, so you lose the intermediate history but not the architecture itself.
Example: Discarding Uploads Older Than One Year
This is the configuration shown above (3) and the one most often asked for. It writes only the uploads of the last year into the backup and leaves out all older coverage, findings and metrics uploads of every project:
- Action:
discard all - of:
External Data - before:
1 year ago - on branches:
.* - and partitions:
.* - for projects:
.*
If you would rather keep a coarse history than none at all, use keep only one per week instead of discard all.
Importing backups
You have three options to import a backup:
The first option is the tab Upload Backup File. Your browser will then let you select a single backup ZIP which you have downloaded previously. Clicking on the Upload Backup button will initiate the import.
The second option is the tab Load Backup From Other Instance. In this case you have to provide the URL and the credentials of another Teamscale instance. The URL of this other instance has to be reachable from your current one. To include only some of the projects from the remote instance, use Fetch Projects to load the remote instance's project list and then select the projects you want. The fetched list contains the projects that the remote user may back up, which the Backup Project Data permission on the remote instance controls. Fetch Projects requires the remote instance to run at least Teamscale 2026.8, because older versions report no backup permission per project. The list is a snapshot, so the import still fails with an error from the remote instance when someone revokes the permission for a selected project after you fetched the list. After clicking on the Import Backup button, the remote Teamscale instance will export a backup which then will be imported on your current instance.
The third option is to provide a file-system path (or S3 URI) to a previously exported backup on the tab Read Backup From File or URL. Then, choose Import Backup to let Teamscale fetch the backup and import it.
Automated backups
For all production uses we highly recommend configuring automated backups. Once configured, Teamscale will regularly perform an automated backup export. This ensures that you can always resort to an up-to-date backup in case of data loss.
Default Automatic Backup Settings
Automatic backups are enabled automatically on the first start of Teamscale using default settings for the backup storage location and for how many backup files will be kept. We recommend revisiting the default settings of automatic backups to make sure that they are in line with your preferences.
To configure automated backups, open the Admin perspective and navigate to Settings > Automatic Backup.  Here you can configure the file name pattern of the backup to be created. Several placeholders can be used to better identify a backup file as described in the description of the settings page. It is recommended to use the
%t placeholder in the file name for reflecting the creation time in the file name.
The "Backup schedule" setting allows to define the frequency of the automatic backups. This setting also defines whether the automatic backup is enabled at all (leave empty to disable). We highly recommend a nightly schedule. To ensure that the backups created do not exceed the disk space available, options exist on how many backups should be preserved for a given interval. For example, you can configure Teamscale to keep daily backups for the last 7 days, weekly backups for the last 5 weeks and monthly backups for 3 months. Teamscale will regularly delete all other backups to free up disk space.
Backup to/from Amazon AWS S3
All aforementioned backup options (including automated backup) also work to/from AWS S3 buckets (or with S3-compatible storage solutions). Instead of specifying a file-system path, you simply specify an S3 URI, e.g., s3://bucket/key or s3+https://acesskey:secretkey@s3.example.com/bucket/path . Rotation settings of automatic backups are also applied to backups stored in S3.
You have two options to specify the path to an S3 bucket: s3 & s3+http(s) URLS.
S3 URLs
Here, the format of the URI is as follows:
s3://<bucket>/<path>To use this URL format, you must set up the machine's AWS environment outside of Teamscale. At a bare minimum, you need to define the access key ID, the access key and the bucket region. If auto-detection of the region used by the AWS client fails, you can override it by setting the system property com.teamscale.aws.region.
S3+HTTP(S) URLS
In this case, the format of the URI is as follows:
(s3+http|s3+https)://[<access key>:<secret key>@]<hostname>[:<port>]/<bucket>/<path>The S3 bucket must be specified as part of the URI's path, not the hostname. In other words, you have to use path-style access rather than virtual-host-style access.
If either access key or secret key contain a slash (/), it must be percent-escaped as %2F.
Instead of providing your access and secret key directly in the URI, it is also possible to store them under Admin > External Accounts. To do so, create an external account entry whose ID and URL both match your chosen hostname and port: http(s)://<hostname>[:<port>]. The entry's Username and Password then are your S3 access key and secret key, respectively.
Storage snapshot backups
Teamscale can be configured to automatically create snapshots of its database.
Configuring Automatic Snapshots
The backups created by Teamscale contain all user generated data (e.g. configurations, architectures, dashboards, and tolerated findings), and uploads (such as coverage data). These backups are useful when migrating to a new version or recovering data that was mistakenly deleted. However, restarting an instance from such a backup requires a reanalysis, which can take some time and might be unsuitable for crash recovery, when fast recovery time is more important.
This gap is filled by storage snapshot backups, which store a snapshot of the entire storage system in one backup file, which has a size that is almost as big as the storage directory. These storage snapshot backups can be created manually in the Backup view of the Admin perspective. It is recommended to configure a regular schedule for creating storage snapshots in the Settings > Automatic Backup view, in the Automatic Storage System Snapshots section. The backup location supports the same placeholders and URI schemes as the normal backup, so storing snapshots in S3 is possible.
Snapshot Support
Note that storage snapshot backups are only supported by these database types: RocksDB, In-Memory (see also Configuring Teamscale on how to configure the database type).
Recovering using a Storage Snapshot
To recover from a crash and start a Teamscale instance from the storage snapshot, you have to start the instance with a specific property. For this, add the following parameter to the jvm.properties config file.
-Dcom.teamscale.snapshot-backup.load-location=LOCATIONPlease note that the import will only be performed, if the storage system is completely empty, to prevent you from accidentally destroying a live instance. In this case, a warning will be logged and the existing instance will be started without any import. Additionally, the version of Teamscale must be the same as the version that was used to create the snapshot. You can not use snapshots during a migration to a newer version of Teamscale.
When working with storage snapshot backups, please consider these general guidelines:
Backups should be stored on a separate machine (or even data center) to prevent data loss in case of disk failures or environmental hazards.
The restore procedure should be tested regularly, both to ensure that all data is available and the steps are known and also to get an idea of how long the restore procedure takes.
Also think about backup procedures for the operating system and hardware for a fallback machine, as in case of a hardware failure, you will also need a new machine to start from.
Think about procedures to switch URLs to a new machine in case of hardware failures, such as load balancers or suitable DNS update strategies.